1. Introduction
This project implements a computer vision system for face detection and person recognition using OpenCV and YOLO (You Only Look Once) deep learning models. It handles both basic face detection in static images and real-time person identification from webcam streams.
Automated face and person recognition is used across domains such as security monitoring, attendance automation, photo editing, and access control systems. This system combines traditional computer vision methods (Haar Cascade classifiers) with deep learning (YOLO) to do both lightweight face detection and model-based person identification.
The system is modular and processes both static images and live video streams, so you can pick the module that fits the task, whether that is simple face detection or model-based person recognition.
Core Features:
- Real-time face detection using webcam streams
- Face detection in static images and video files
- Custom person recognition using trained YOLO models
- Real-time person identification through live camera input
- Batch processing support for images and videos
2. Methodology / Approach
The project employs two distinct approaches for computer vision tasks:
Face Detection: Utilizes OpenCV's Haar Cascade classifier (haarcascade_frontalface_default.xml), a machine learning-based approach where a cascade function is trained with positive and negative images. This traditional method is computationally efficient and suitable for basic face detection tasks.
Person Recognition: Implements YOLO (You Only Look Once) deep learning models, specifically custom-trained versions for identifying specific individuals. The YOLO architecture processes the entire image in a single forward pass, making it suitable for real-time applications while maintaining high accuracy.
2.1 System Architecture
The system is organized into five independent modules, each designed for specific use cases:
- Static Image Processing: Face detection in individual photos
- Video File Processing: Face detection in pre-recorded videos
- Real-time Face Detection: Live face detection using webcam
- Trained Model Recognition: Person identification in photos and videos using custom YOLO models
- Real-time Person Recognition: Live person identification using webcam
2.2 Implementation Strategy
Each module is implemented as a standalone Python script, allowing flexible deployment based on requirements. The face detection modules use OpenCV's pre-trained Haar Cascade classifier for rapid detection, while person recognition modules leverage Ultralytics YOLO framework with custom-trained models for specific individual identification. All real-time modules include graceful exit mechanisms (press 'q' to quit) and proper resource cleanup.
3. Mathematical Framework
3.1 Haar Cascade Detection Algorithm
The Haar Cascade classifier uses a cascade of weak classifiers to detect faces through sliding window approach:
$$F(x) = \begin{cases} 1 & \text{if } \sum_{i=1}^{n} \alpha_i h_i(x) \geq \theta \\ 0 & \text{otherwise} \end{cases}$$
where:
- $F(x)$ = final classification decision (1 = face detected, 0 = no face)
- $h_i(x)$ = weak classifier $i$ decision
- $\alpha_i$ = weight of classifier $i$
- $\theta$ = classification threshold
- $n$ = number of weak classifiers in the cascade
3.2 Haar-like Features
Rectangular features calculated as difference between sum of pixels in adjacent regions:
$$f_{\text{haar}} = \sum_{\text{white region}} I(x,y) - \sum_{\text{black region}} I(x,y)$$
where $I(x,y)$ represents pixel intensity at position $(x,y)$.
3.3 Integral Image for Fast Computation
The integral image allows fast feature calculation:
$$II(x,y) = \sum_{x' \leq x, y' \leq y} I(x',y')$$
Any rectangular sum can be computed in constant time:
$$\text{Sum} = II(D) + II(A) - II(B) - II(C)$$
where $A, B, C, D$ are corners of the rectangle.
3.4 YOLO Detection Framework
YOLO divides the image into $S \times S$ grid and predicts bounding boxes:
$$P(\text{object}) \times IOU_{\text{pred}}^{\text{truth}} = \text{Confidence Score}$$
Bounding Box Prediction:
$$\text{bbox} = (x, y, w, h, \text{confidence}, c_1, c_2, ..., c_n)$$
where:
- $(x, y)$ = center coordinates relative to grid cell
- $(w, h)$ = width and height relative to image
- $\text{confidence}$ = $P(\text{object}) \times IOU$
- $c_i$ = class probabilities
3.5 Non-Maximum Suppression (NMS)
YOLO uses NMS to eliminate redundant detections:
$$\text{IoU}(box_i, box_j) = \frac{\text{Area}(box_i \cap box_j)}{\text{Area}(box_i \cup box_j)}$$
Boxes with $\text{IoU} > \text{threshold}$ are suppressed if their confidence is lower than the maximum.
3.6 Loss Function for YOLO Training
The YOLO loss function combines localization, confidence, and classification losses:
$$\mathcal{L} = \lambda_{\text{coord}} \mathcal{L}_{\text{box}} + \lambda_{\text{obj}} \mathcal{L}_{\text{obj}} + \lambda_{\text{noobj}} \mathcal{L}_{\text{noobj}} + \lambda_{\text{class}} \mathcal{L}_{\text{class}}$$
where:
- $\mathcal{L}_{\text{box}}$ = bounding box coordinate loss (MSE)
- $\mathcal{L}_{\text{obj}}$ = objectness loss for cells containing objects
- $\mathcal{L}_{\text{noobj}}$ = objectness loss for cells without objects
- $\mathcal{L}_{\text{class}}$ = classification loss (cross-entropy)
- $\lambda_i$ = weighting coefficients
3.7 Performance Metrics
Precision: Proportion of correct positive predictions
$$\text{Precision} = \frac{TP}{TP + FP}$$
Recall: Proportion of actual positives correctly identified
$$\text{Recall} = \frac{TP}{TP + FN}$$
F1 Score: Harmonic mean of precision and recall
$$F_1 = 2 \times \frac{\text{Precision} \times \text{Recall}}{\text{Precision} + \text{Recall}}$$
Mean Average Precision (mAP):
$$\text{mAP} = \frac{1}{N} \sum_{i=1}^{N} AP_i$$
where $AP_i$ is the average precision for class $i$.
4. Requirements
requirements.txt
numpy>=1.19.0
opencv-python>=4.5.0
ultralytics>=8.0.0
5. Installation & Configuration
5.1 Environment Setup
# Clone the repository
git clone https://github.com/kemalkilicaslan/Face-Detection-and-Person-Recognition-System.git
cd Face-Detection-and-Person-Recognition-System

# Install required packages
pip install -r requirements.txt
5.2 Project Structure
Face-Detection-and-Person-Recognition-System
├─ Detect-Faces-in-Photo.py
├─ Detect-Faces-in-Video.py
├─ Real-Time-Face-Detection.py
├─ Real-Time-Person-Recognition.py
├─ Person-Recognition-in-Photo-and-Video.py
├─ haarcascade_frontalface_default.xml
├─ Dockerfile
├─ .dockerignore
├─ docker-compose.yml
├─ .gitignore
├─ README.md
├─ requirements.txt
└─ LICENSE
5.3 Required Files
For Face Detection:
haarcascade_frontalface_default.xml- Download from OpenCV GitHub repository or included in OpenCV installation
For Person Recognition:
- Custom trained YOLO model files (
.ptformat)- Example:
Kemal-Kilicaslan.pt - Example:
How-I-Met-Your-Mother-Person-Recognition-model.pt
- Example:
6. Usage / How to Run
6.1 Face Detection in Photo
python Detect-Faces-in-Photo.pyRequirements:
- Input image:
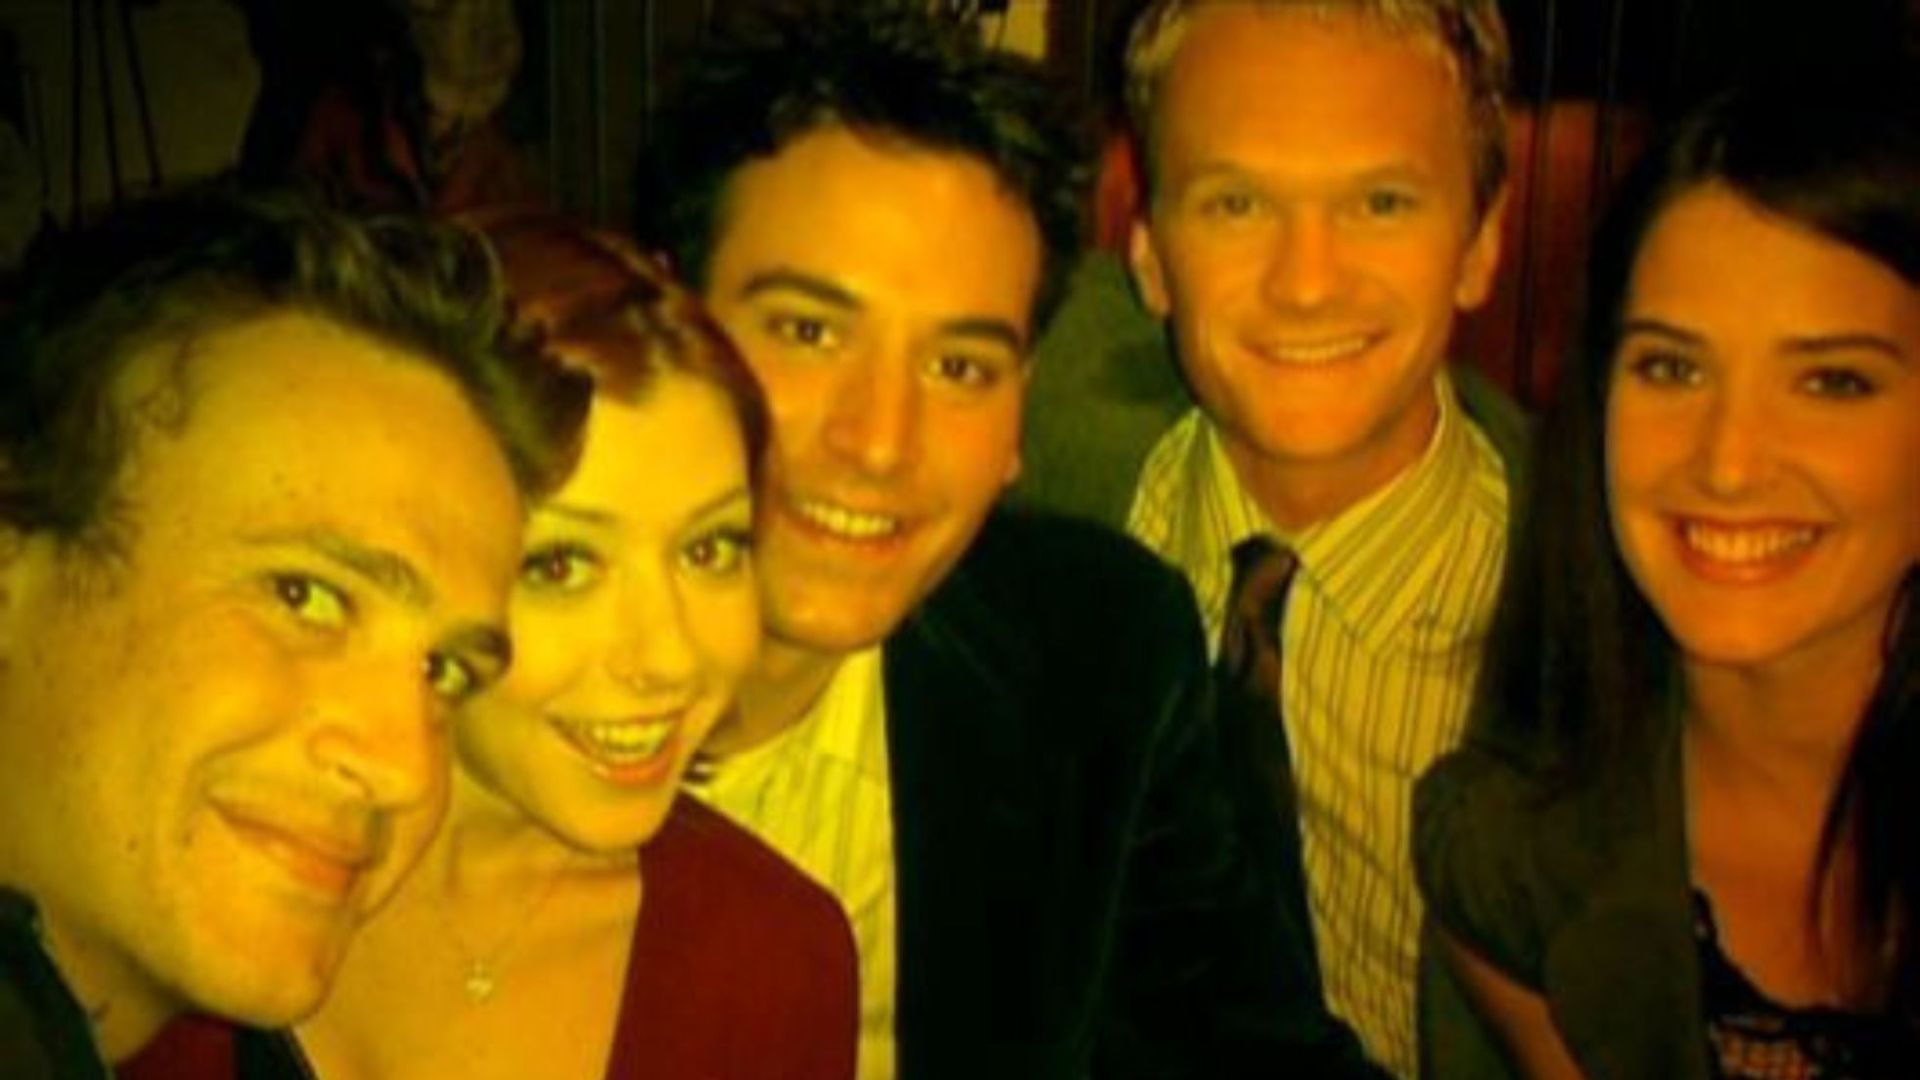
HIMYM.jpg(modify in script) - Output:
HIMYM-faces-detected.jpg
6.2 Face Detection in Video
python Detect-Faces-in-Video.pyRequirements:
- Input video:
HIMYM.mp4(modify in script) - Output:
HIMYM-faces-detected.mp4
6.3 Real-Time Face Detection
python Real-Time-Face-Detection.pyControls:
- Press
qto quit the application - Requires active webcam (camera index 0)
6.4 Person Recognition in Photo/Video
python Person-Recognition-in-Photo-and-Video.pyConfiguration:
- Uncomment the appropriate line for photo or video processing
- Modify model path and input file paths as needed
6.5 Real-Time Person Recognition
python Real-Time-Person-Recognition.pyRequirements:
- Custom trained YOLO model:
Kemal-Kilicaslan.pt - Active webcam connection
Controls:
- Press
qto exit
7. Docker Deployment
The system can be packaged and run in a container so that the code, its dependencies and the runtime environment stay consistent across machines.
Files
Dockerfile- builds the image (Python 3.11 + OpenCV/ffmpeg system libraries + Python dependencies)..dockerignore- keeps large media and model files out of the build context.docker-compose.yml- runs the container and mounts the project folder for input/output.
Build and run
docker compose up --build

# or with the Docker CLI directly
docker build -t face-detection-person-recognition:latest .
docker run --rm -v "$(pwd)":/app face-detection-person-recognition:latest
Notes
- This project contains several scripts. The default container command runs
Detect-Faces-in-Photo.py. To run a different one, override the command:
  docker compose run --rm face-detection python Detect-Faces-in-Video.py
docker compose run --rm face-detection python Person-Recognition-in-Photo-and-Video.py- The
Real-Time-Face-Detection.pyandReal-Time-Person-Recognition.pyscripts read from a local webcam (VideoCapture(0)) and are not intended to run inside a container. - Input media and model files are shared through the bind mount, so results appear on the host after the run.
- The scripts call
cv2.imshow, which needs a graphical display. On a headless server the output files are still written to disk; the live preview window is only available on Linux with X11 forwarding (see the commented lines indocker-compose.yml).
8. Application / Results
8.1 Face Detection in Photo
Input Image:
Output Image:

8.2 Person Recognition in Photo
Input Image:

Output Image:

8.3 Face Detection in Video
Input Video:
Output Video:
8.4 Person Recognition in Video
Input Video:
Output Video:
8.5 Real-Time Face Detection
Demo Video:
8.6 Real-Time Person Recognition
Demo Video:
9. Tech Stack
9.1 Core Technologies
- Programming Language: Python 3.7+
- Computer Vision: OpenCV 4.5+
- Deep Learning Framework: Ultralytics YOLO 8.0+
- Object Detection: YOLOv8 (You Only Look Once)
9.2 Libraries & Dependencies
| Library | Version | Purpose |
|---|---|---|
| opencv-python | 4.5+ | Image processing, video capture, and face detection |
| ultralytics | 8.0+ | YOLO model implementation and inference |
| numpy | 1.19+ | Array operations (dependency) |
9.3 Pre-trained Models
Haar Cascade Classifier:
- Model:
haarcascade_frontalface_default.xml - Architecture: Viola-Jones object detection framework
- Training: Pre-trained on thousands of positive and negative face samples
- Detection Type: Frontal face detection
- File Size: ~900 KB
Custom YOLO Models:
- Architecture: YOLOv8 (customizable: n, s, m, l, x variants)
- Training: Custom datasets of specific individuals
- Format: PyTorch (.pt) model files
- Detection Type: Person-specific recognition
- File Size: Varies (5-100 MB depending on variant)
10. License
This project is licensed under the Creative Commons Attribution-NonCommercial-NoDerivatives 4.0 International (CC BY-NC-ND 4.0).
11. References
- OpenCV Cascade Classifier Tutorial Documentation.
- OpenCV Haar Cascade Classifiers GitHub Repository.
- Ultralytics YOLOv8 Documentation.
Acknowledgments
Thanks to the OpenCV and Ultralytics communities for their computer vision tools and documentation. Sample images and demonstrations use content from "How I Met Your Mother" for educational purposes only. The Haar Cascade classifier was introduced by Viola and Jones (2001). Person recognition here uses Ultralytics YOLOv8.
Note: Ensure you have proper permissions and comply with privacy regulations when using facial recognition technology in production environments. This system is intended for educational and research purposes in controlled settings. Always respect individual privacy rights and obtain appropriate consent before deploying face recognition systems. Consider ethical implications and potential biases in facial recognition technology.